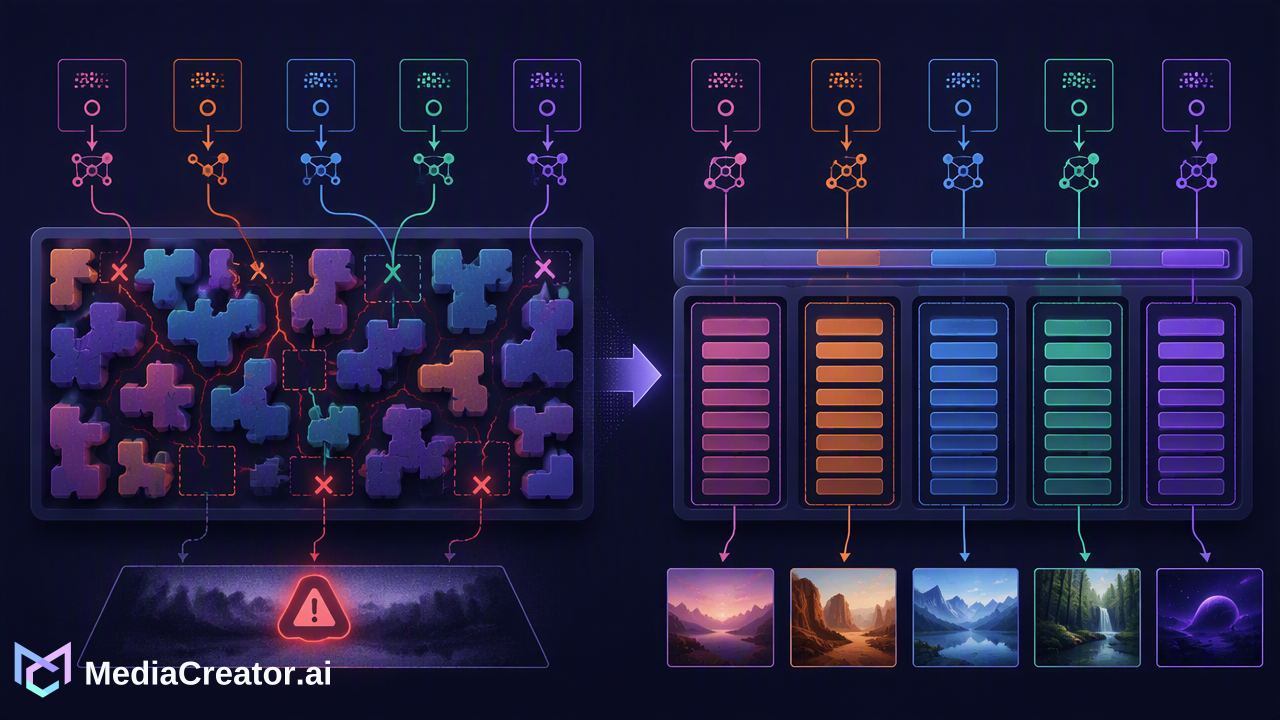
Optimizing Frame-Level Consistency in Asynchronous Generative Video Pipelines
Achieving temporal stability in generative video requires decoupling the inference execution from the frame-stitching process through a robust message-queue architecture and deterministic seed management.
The Challenge of Temporal Jitter in Distributed Inference
When building a distributed system for generative video, the primary goal is often throughput. You want to parallelize the generation of individual frames across a cluster of GPU nodes to minimize the time-to-video. However, a common pitfall occurs when the system treats video generation as a collection of independent tasks rather than a coherent, time-ordered sequence.
In a typical naive implementation, a producer service dispatches frame-generation requests to a cluster. Each worker node processes its assigned frame and pushes the result to a storage bucket. A downstream stitching service then polls the bucket, waiting for all frames to arrive before concatenating them into a video file.
The problem arises when inference latency is non-deterministic. Because GPU load, network congestion, and cold-start times vary, frame 10 might finish before frame 2. If the stitching service is not strictly sequence-aware, or if it attempts to "fill in the gaps" as frames arrive, you encounter temporal jitter. This manifests as flickering—where the visual content of frame N does not transition smoothly into frame N+1 because the underlying latent state was not properly synchronized or the frames were stitched out of order.
Diagnosing the Race Condition
The "flickering" artifact is rarely a failure of the generative model itself; it is usually a failure of the orchestration layer. If your inference pipeline relies on a stateless architecture where each frame is generated in isolation, you lose the temporal coherence required for fluid motion.
Consider a scenario where you use a seed-based generation approach. If the worker responsible for frame 5 receives a request with a different global seed or a misaligned latent vector compared to frame 4, the output will diverge sharply. Even if the seeds are correct, if the stitching service begins assembling the video before all frames are finalized, it may attempt to read a partially written file or a stale cache entry, leading to visual artifacts.
Furthermore, API rate limits often complicate this. If your infrastructure hits the request-per-minute or concurrency limits imposed by your inference provider, the system may experience backpressure. If your stitching service is not designed to handle this backpressure, it might time out or proceed with a partial set of frames, resulting in a stuttering video. Always consult the current API documentation for the specific limits applicable to your environment.
Decoupling Execution with a Message-Queue Architecture
To solve this, you must decouple the inference execution from the frame-stitching process. Instead of having workers write directly to a final storage location, introduce a message-queue-based architecture that enforces strict ordering.
- The Sequencer: Before dispatching tasks, a central coordinator generates a sequence manifest. This manifest assigns a unique
frame_indexand a deterministicseed_offsetto every frame. - The Queue: Use a message broker (such as RabbitMQ or a managed streaming service) to distribute these tasks. Each worker consumes a task containing the
frame_indexand theseed_offset. - The Buffer: Instead of writing to the final video file, workers write to a temporary, indexed storage area.
- The Stitcher: The stitching service acts as a consumer that only triggers once the message queue confirms that all
frame_indexvalues for a specificvideo_idhave been processed and acknowledged.
This architecture ensures that the stitching service never sees an incomplete or out-of-order dataset. By using a centralized state coordinator, you maintain a "source of truth" for the progress of each video generation job.
Implementing Deterministic Seed Management
Temporal stability requires that the generative model receives consistent inputs across the sequence. If you are using a diffusion-based model, the latent noise must be correlated between frames.
A common mistake is to generate a random seed for every frame. Instead, implement a deterministic seed derivation function:
def get_frame_seed(base_seed, frame_index, temporal_factor):
    # Use a hash-based approach to ensure frame N
    # is always generated with the same seed given the same base
    return hash(f"{base_seed}_{frame_index}_{temporal_factor}")
By passing this derived seed to the inference worker, you ensure that even if the worker is restarted or the request is retried, the output for frame_index remains identical. This eliminates the "flicker" caused by random noise variance.
The Stitching Service: A Sequence-Aware Consumer
The stitching service should be a state machine. It should track the status of each frame in a database (e.g., Redis or PostgreSQL). A frame is only marked as "ready" when the worker has successfully written the output to the temporary store and acknowledged the message in the queue.
# Pseudo-code for a sequence-aware stitcher
def check_and_stitch(video_id):
    frames = db.get_frames_for_video(video_id)
    if all(f.status == 'COMPLETED' for f in frames):
        # Sort by frame_index to ensure correct order
        sorted_frames = sorted(frames, key=lambda x: x.frame_index)
        ffmpeg_stitch(sorted_frames)
    else:
        # Log progress and wait for remaining frames
        log.info(f"Waiting for frames: {count_pending(frames)}")
Trade-offs and Limitations
This approach introduces a significant trade-off: latency vs. consistency. By waiting for all frames to be processed before stitching, you increase the total time-to-video. If one worker node fails or experiences a network partition, the entire video generation job is blocked.
To mitigate this, implement a "dead-letter queue" or a retry mechanism. If a frame fails to process after a set number of attempts, the coordinator should trigger a re-generation of that specific frame rather than failing the entire job.
Another limitation is storage overhead. Storing individual frames in a temporary buffer requires significant I/O and storage capacity. For high-resolution video, this can become a bottleneck. You may need to implement a cleanup policy that deletes temporary frames immediately after the final video is rendered.
Key Takeaways
- Decouple to Stabilize: Separate the inference execution from the stitching process using a message queue to prevent race conditions.
- Deterministic Seeds: Use a deterministic seed derivation function to ensure that frames are generated with consistent latent noise, preventing visual jitter.
- Stateful Stitching: Treat the stitching service as a state machine that only triggers once the sequence manifest is fully satisfied.
- Handle Backpressure: Be mindful of API rate limits and concurrency constraints; design your queue to handle retries and backpressure gracefully rather than failing the entire pipeline.
- Monitor the Sequence: Use a database to track the status of individual frames, allowing for granular retries instead of full-job restarts.