Resolving CUDA Out-of-Memory Errors in Multi-Stage Inference Pipelines
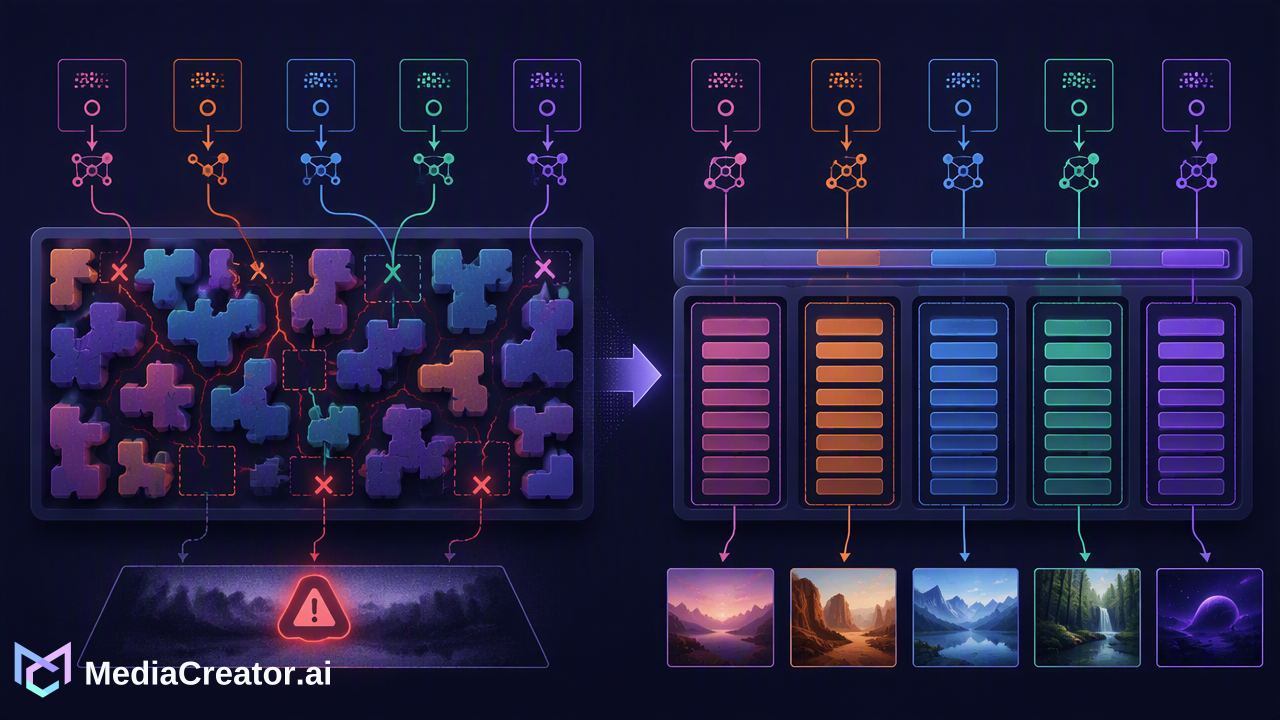
When chaining multiple generative models, static memory allocation often fails due to fragmentation; implementing a dynamic memory reclamation strategy and context-aware buffer management is essential for system stability.
Sep 17, 20266 min read